Natnael Alemseged
AboutProjectsClient OutcomesWork Experience
© 2026 Natnael Alemseged. All Rights Reserved.
Applied AI // Evaluation-Driven // Built in Addis Ababa
AVAILABLE FOR NEW CONTRACTS

Hi, I am NatnaelAlemseged

Applied AI Engineer | Agent Systems, Evaluation & Production AI

I build reliable agentic systems, evaluation-driven RAG pipelines, and production AI products—taking them from ambiguous requirements through deployment, observability, and measurable iteration.📍 Based in Addis Ababa (EAT / UTC+3) — Open to remote roles worldwide and relocation for onsite Applied AI opportunities.

View Core WorkContact System
SHIPPED APPS

30+

USERS REACHED

10K+

DEV CONTRACTS

5yr+

Python
FastAPI
Next.js
Flutter
Docker
Qdrant
Natnael Alemseged
VALUE_PROPOSITION

Turning AI capabilities into reliable product outcomes.

I'm an Applied AI Engineer specializing in agentic systems, evaluation, RAG, and full-stack product delivery. I connect modern models to dependable APIs and thoughtful user experiences that solve concrete business problems.

Whether I'm shaping an ambiguous requirement, implementing an MCP integration, designing a retrieval pipeline, or shipping the final interface, I engineer for reliability, measurable quality, and real-world use.

“Useful AI is more than a model call—it is a system that can be measured, trusted, and improved.”

CORE_COMMITMENTS

PROVEN_UTILITY

01.Problem Framing & Evaluation

What: Defining user outcomes, representative eval sets, quality thresholds, and failure categories before scaling a solution.

Why: Turns subjective AI demos into measurable product behavior and clear release decisions.

02.Production AI Systems

What: Combining agents, retrieval, structured generation, and model integrations with dependable Python and TypeScript services.

Why: Keeps model behavior observable, bounded, and useful under real product constraints.

03.End-to-End Product Delivery

What: Shipping the interface, APIs, data flows, cloud infrastructure, monitoring, and feedback loops around the AI capability.

Why: Moves the work from a promising prototype to a product people can adopt and improve.

SECURE_COMPILER_OKVER_2026.05
DELIVERY_EVIDENCE
30+

Projects Shipped

AI, web, and mobile products delivered

10K+

Users Reached

People served by production systems

65%

Bug Reduction

Production defects reduced through typed workflows

30%

Efficiency Gain

Team productivity gained from agent workflows

Applied AI capabilities

From model behavior to production

A delivery stack organized around the work: evaluate model behavior, connect retrieval and tools, build dependable services, ship the product surface, and observe it in production.

LangGraph
Multi-Agent Systems
LLM-as-a-Judge / Evals
Benchmark Design
Fine-tuning & Preference Data
Structured Generation
MCP & Tool Use
LangFlow

33 production capabilities across the AI lifecycle

applied_ai_method

How I Build Applied AI, End to End

I turn ambiguous product goals into measurable AI behavior—aligning with users, designing the system, validating model quality, and shipping the complete production experience.

applied-ai@natnael: ~ (production_env)
OPERATIONAL_PROTOCOL_OK
>applied-ai frame --target user-outcome
Mapping users, decisions, data, and operating constraints...
✅ Target behavior and non-goals documented
✅ Representative examples converted into an evaluation set
✅ Quality, latency, and cost thresholds agreed
EXECUTION_STATE: NATNAEL_ACTIVE
Stakeholder alignment: 100%

Frame the Decision, Not Just the Demo

I translate user needs and business constraints into a testable AI behavior, an evaluation set, and a clear definition of useful before implementation expands.

Build with Evidence Loops

I combine strict Pydantic and TypeScript contracts with targeted evaluations, observable workflows, and explicit failure handling so AI behavior can be measured and improved.

Ship the Whole Product System

I connect model and retrieval behavior to backend services, data flows, interfaces, deployment, and production feedback so the AI capability survives contact with users.

Selected Applied AI Work

Applied AI & Product Systems

Case studies showing how I turn models, data, evaluations, and full-stack engineering into production systems with measurable behavior.

Explore Full Archive (26)→
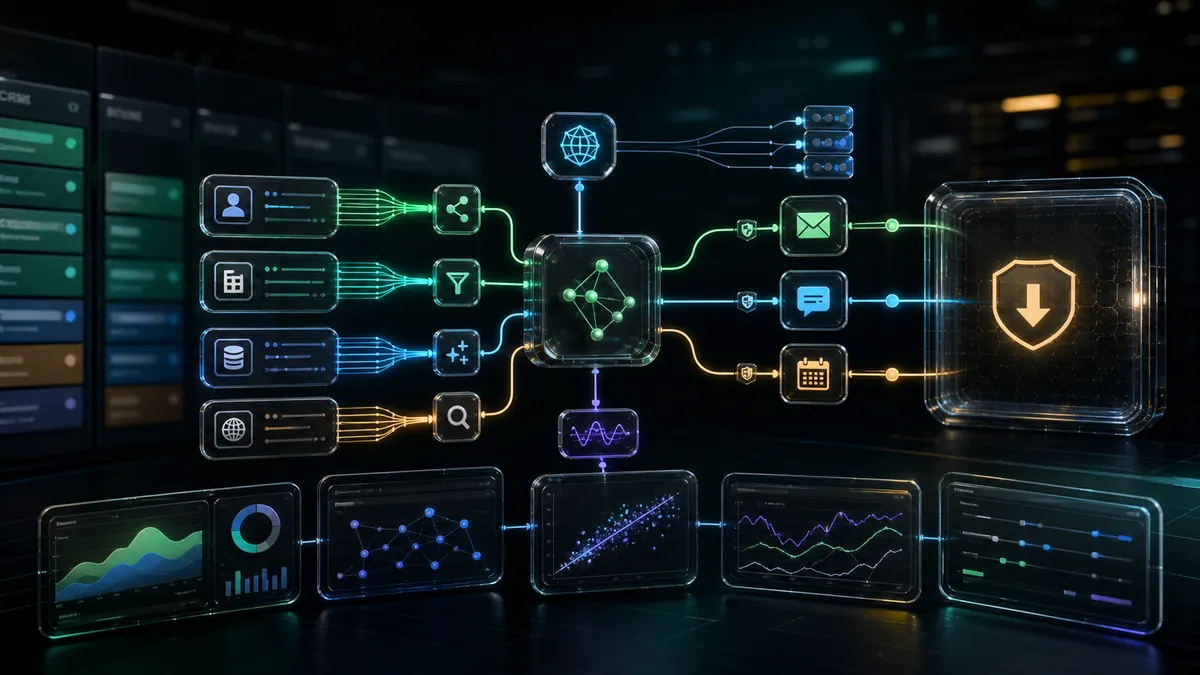
Tenacious Conversion Engine safety-routed outreach workflow
Software Application

Tenacious Conversion Engine

FastAPI sales automation engine for synthetic-prospect outreach, combining inbound email/SMS webhooks, HubSpot write-back, Cal.com booking, enrichment signals, Langfuse traces, and tau2-bench evaluation.

“Built the sales agent with sink-routed outbound safety and sealed-eval guardrails before any live-channel workflow.”

FastAPIPythonHubSpot APICal.com+2 more
Read Case Study→
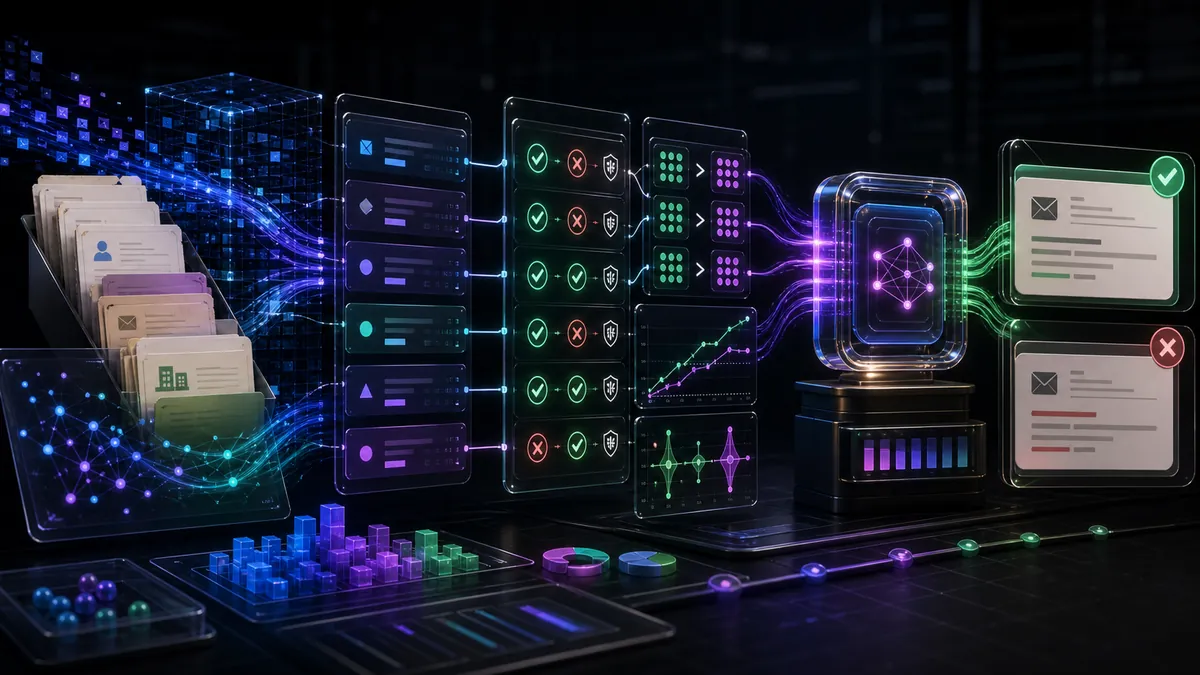
SalesConversion-Bench evaluation and trained critic pipeline
Creative Work

SalesConversion-Bench

Sales-domain benchmark and trained critic layer for Tenacious-style B2B outreach, with contamination-aware task generation, deterministic scoring checks, preference data, and a small LoRA judge.

“Turned prospect-facing sales failures into a measurable benchmark and judge gate instead of trusting generated drafts by default.”

PythonJSON SchemaLoRASimPO+2 more
Read Case Study→
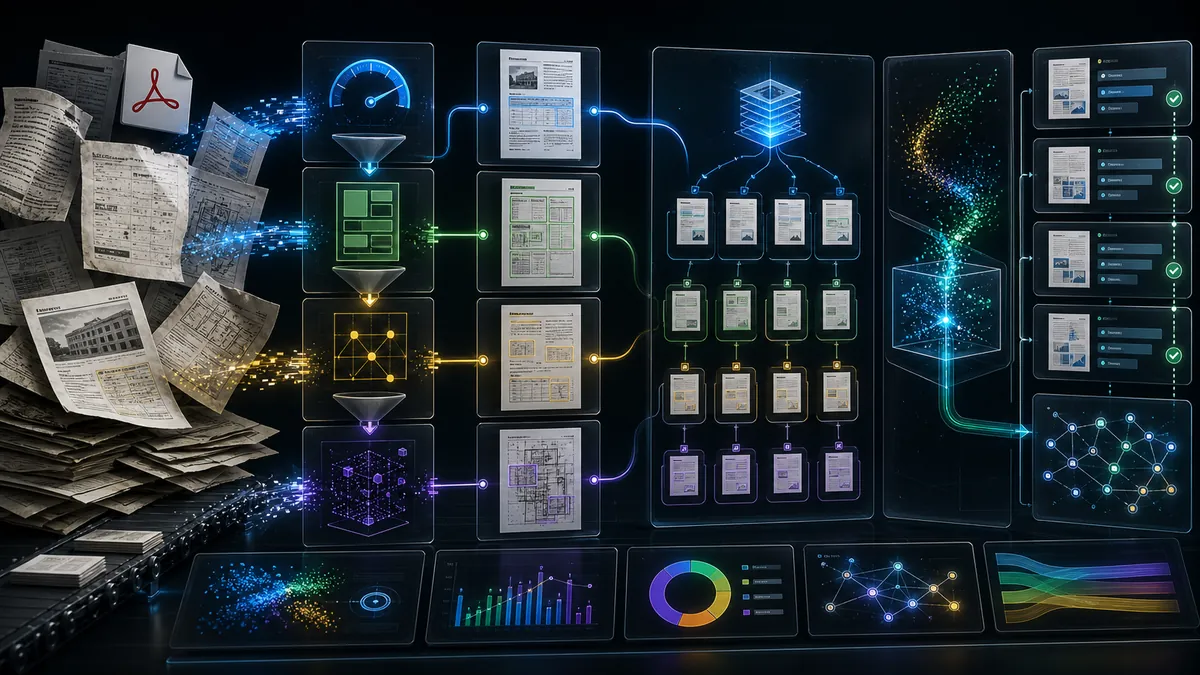
Document Intelligence Refinery confidence-gated PDF extraction pipeline
Software Application

Document Intelligence Refinery

PDF triage and extraction pipeline that detects document origin, layout, and domain, escalates extraction strategies by confidence, builds PageIndex trees, and answers with provenance chains.

“Converted messy PDFs into auditable structured facts with confidence gates, retrieval indexes, and source-cited answers.”

PythonPydanticDoclingLangGraph+2 more
Read Case Study→
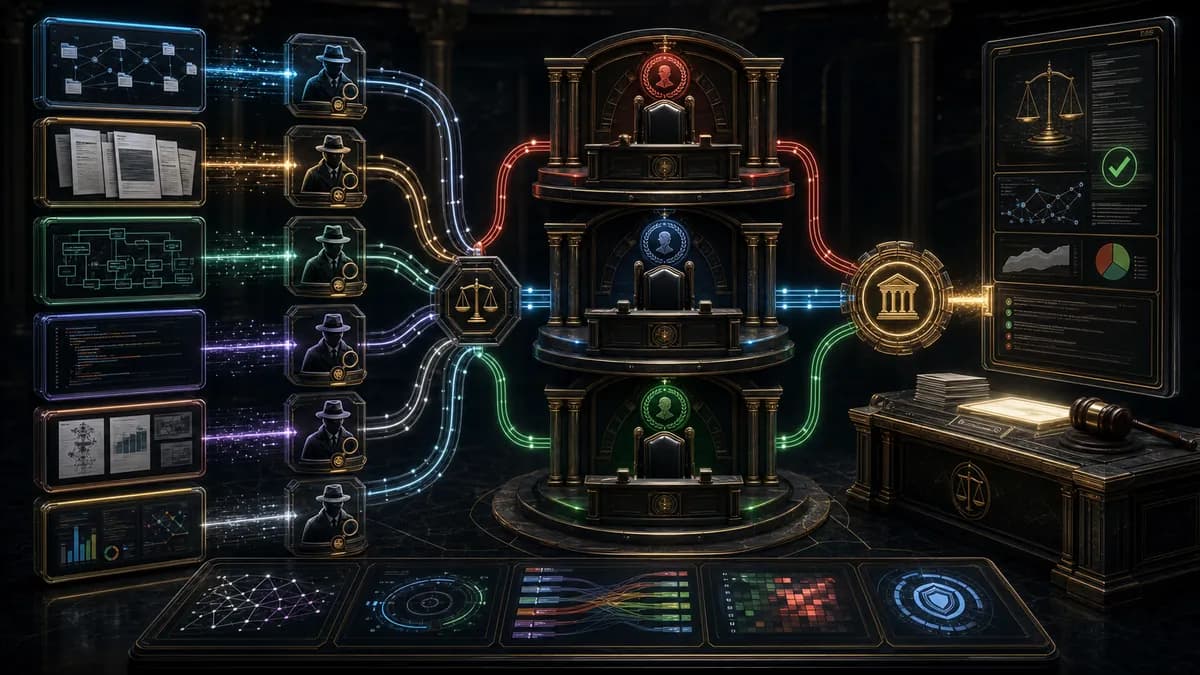
GitHub Evaluator forensic codebase audit workflow
Software Application

GitHub Evaluator / Automaton Auditor

LangGraph forensic codebase evaluator using a Digital Courtroom protocol: evidence-gathering detectives, three judge personas, deterministic conflict resolution, and hallucination policing.

“Made repository evaluation adversarial and evidence-bound instead of letting a single judge model grade from vibes.”

LangGraphPythonRAGAST Analysis+2 more
Read Case Study→
AI-Workspace real-time streaming dashboard
Web Application

AI-Workspace

Engineered a modular, production-grade backend framework designed specifically to power AI workspaces. Implements robust token caching, graceful rate-limit handling, circuit breakers, and WebSockets for real-time state streaming.

“High-performance, async-first engine for long-running agentic processes and real-time streaming.”

FastAPIAsyncioRedisPostgreSQL+2 more
Read Case Study→
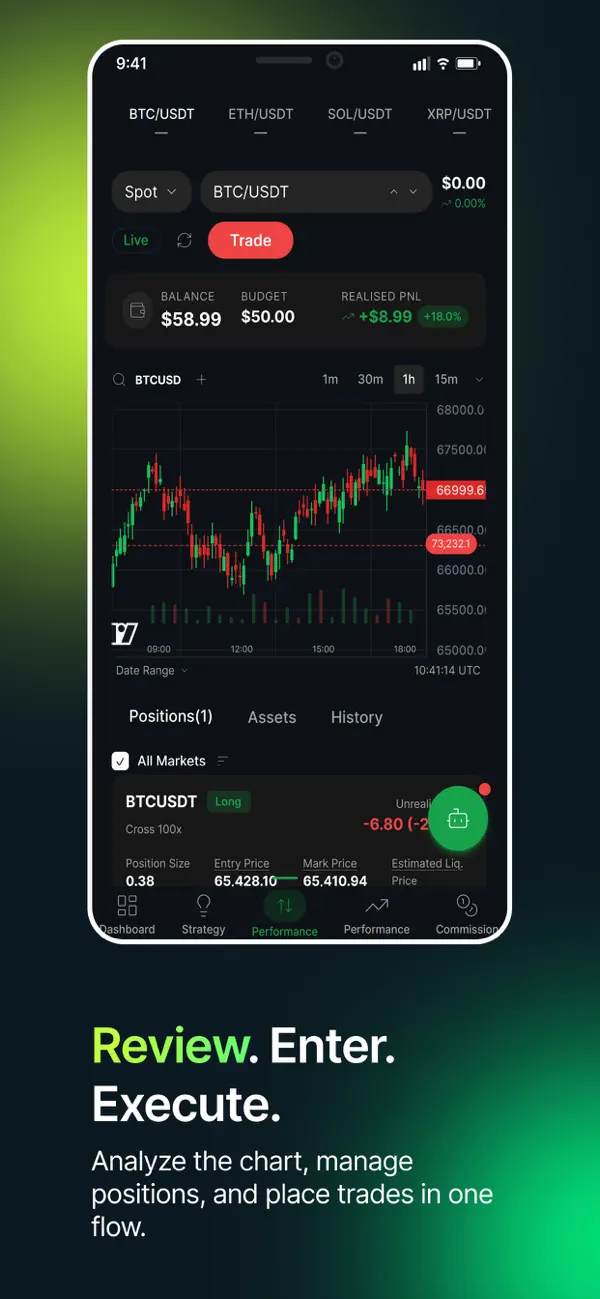
TapTrade Boingo app icon
TapTrade Boingo market overview
Mobile Application

TapTrade Boingo — AI-Assisted Crypto & Prediction-Market Trading

A fast mobile trading app for crypto and prediction markets with AI-assisted insights, live market data, interactive charts, paper trading, risk controls, strategy review, and performance monitoring.

“Built an Expo/React Native trading client that balances fast multi-market access with AI decision support, simulation, persistent state, secure storage, and disciplined risk tooling.”

React NativeExpo 54TypeScriptExpo Router+7 more
Read Case Study→

Full Archive

View all 26 projects and case studies

Browse Everything →
5 published research notes

Technical Writing & AI Research

Reproducible explanations of the evaluation, alignment, and inference decisions behind production LLM systems—not a glossary of AI terminology.

May 2, 2026

When Generic Benchmarks Fail: Building a Sales-Domain Evaluation Bench from Scratch

A production case study in turning domain failures into a measurable benchmark: contamination-aware task generation, deterministic checks, human grading, preference data, and a trained judge.

240
evaluation tasks
4
task-generation sources
+76.6pp
held-out judge lift
Benchmark DesignLLM-as-a-JudgePreference Data
Read analysis
May 8, 2026

Why Pairing Your Bootstrap Is Necessary, And When It Stops Helping

A first-principles explanation of paired versus unpaired bootstrap designs for LLM evaluation, backed by Python simulation and an explicit variance analysis.

8.4%
paired SE reduction
r = 0.167
observed covariance
2
sampling designs compared
Statistical EvaluationBootstrapPython
Read analysis

DPO vs SimPO: What Your Preference Trainer Is Actually Optimizing

May 7, 2026

Objective functions, length bias, reference-free optimization, gradient behavior, and VRAM tradeoffs for preference tuning.

Fine-tuningDPOSimPO

"Return JSON only" Doesn't Force JSON. Here's What Actually Forces It.

May 6, 2026

Why prompt instructions are weaker than constrained decoding, schema enforcement, and token-level generation controls.

Structured OutputLogitsConstrained Decoding

Why Merged LoRA Barely Changes Inference Time

May 5, 2026

A systems-level explanation of adapter merging, parameter updates, runtime graph shape, and where LoRA inference overhead actually appears.

LoRAInferenceFine-tuning

The research layer of my Applied AI practice: methods I can explain, reproduce, test, and carry into production systems.

View DEV profile

Verified Delivery

Evidence from shipped work.

Verified Upwork delivery

Delivered a complete social music party-game product engagement from implementation through client handoff.

Verified client engagement

January–June 2026

Project

Social Music Party Game

Impact

Verified 5.0 Upwork rating

30+

projects shipped

10K+

users reached

65%

bug reduction

Discuss an AI project

Production Experience

Experience.

A progression from product and platform engineering into production AI—combining model integration, backend reliability, and end-to-end delivery.

Connect

Need an AI system that works
beyond the prototype?

Tell me about the users, workflow, data, and quality bar. I can help frame the problem, build the system, and create the evaluation loop around it.

EmailLinkedIn

Send a Message

Share the problem, current system, and what a successful outcome looks like.